Code and Report at Github
Flight delays are on a steady rise, presenting significant financial challenges and fostering
dissatisfaction among airline companies’ customers. Addressing this pressing issue, the
study employed supervised machine learning models to forecast flight delays.
Four algorithms - Logistic Regression, K-Nearest Neighbor, Random Forest, and
XGBoost were trained and tested to complete the binary classification of flight delays. The
evaluation of algorithms was fulfilled by comparing the values of four measures: accuracy,
precision, recall, and f1-score.
These measures were weighted to adjust the imbalance of the
selected data set. The comparative analysis showed that the XGBoost algorithm has the
best performance with an accuracy of 63% and KNN has the worst performance with an F1
Score of 58%. Tree-based ensemble classifiers generally have better performance than other
base classifiers.
Kaggle
with 28 features and 5.81M instances describing diverse aspects of flight information crucial in determining the performance and reliability of air transportation.
The dataset is sourced from Kaggle and encompasses a vast repository of airline delay and cancellation data, offering a comprehensive perspective on the operational challenges faced by the aviation industry from 2009 to 2018. For our study, we have specifically focused on data from the year 2015, providing insights into the performance and reliability of air transportation services during this period.
The dataset consists of a total of 5,819,079 rows and 28 columns. This includes a broad spectrum covering temporal dynamics, operational details, geo-spatial information, and delay classifications.
The dataset comprises integer and categorical (including binary) data types, reflecting various essential information crucial for investigating airline delays. This extensive dataset presents abundant opportunities for thorough examination and analysis, facilitating a detailed exploration of airline delays and cancellations.
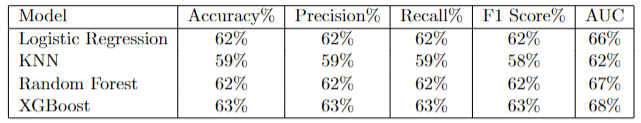
The XGBoost model demonstrates the most promising performance among the models tested with an accuracy of 68\%, and the highest AUROC and minimal overfitting as indicated by the learning curve analysis. This suggests that the XGBoost model is well-suited for predicting flight delays based on the features provided in the dataset, ensuring effective flight delay management for improved operational efficiency and passenger satisfaction.
Recommendations
The dataset offers valuable insights useful for strategic planning within the airline industry
for them to optimize route planning and resource allocation. This enhances operational
efficiency and contributes to customer satisfaction which are vital in the airline industry.
The model’s predictions help airlines manage their resources better. From staffing to
maintenance and fuel, these forecasts allow airlines to make wise decisions, saving costs and
boosting profits. By matching resources with the demand, airlines can run their operations
smoothly and achieve better financial results.
We recommend the implementation of targeted strategies to address delays on routes prone to disruptions. By adjusting flight
schedules and allocating resources strategically, airlines can mitigate the impact of delays.
Also, investing in preventive maintenance programs to address underlying issues could be
helpful. These measures help reduce delays and improve customer satisfaction.
Model Critique
The project began with the aim of employing regression models to predict flight delays
which was a continuous variable rather than being binary. However, as we delved deeper
into the data and its analysis, we encountered several limitations and challenges that
reformed our approach.
One significant problem was we noticed the inherent skewness or asymmetry in the
distribution of departure delay data. This skewed distribution posed a challenge for our
regression models, as they struggled to capture the variance of the data accurately because
they require normally distributed or at least symmetric data. Figure 17 depicts the
right-skewness or asymmetry observed with the continuous departure delay variable.
In addition to challenges related to data distribution, the lack of critical features such as
detailed air traffic information and explicit causes of the delays such as weather or NAS
delays also severely limited our models’ ability to make precise predictions. These essential
features were initially included in the dataset but were later removed due to their high
sparsity. With over 98% of the data containing null values, these features became redundant
and were removed.
The results of the regression models were highly unsatisfactory indicating that only 3.5% of
the variance in the data could be accounted by the predictions. Therefore, we transitioned
towards classification models, which offered a better framework for addressing the data’s
complexities. The departure delay was converted to a binary variable indicating delay for a
positive departure delay value and not otherwise. Despite this, the challenges continued,
emphasizing the need for better solutions to overcome them.
The scale of the dataset presented logistical challenges during the training process. Training
our models on such a large dataset required substantial computational resources and time.
Although Google Colab was used for training the model with its processor and RAM, the
training time of the models did not vary.
Additionally, Google Colab’s RAM would reach
full capacity when attempting to use more training data, so the dataset was reduced. 200000
delayed and non-delayed flights each were sampled for training and testing the model
further. Moreover, including hyperparameter tuning to optimize model performance added
another layer of complexity, extending the training time even further. We tried to run a
Support Vector Machine (SVM) model for fitting the data and classifying the flights as
delayed or not. However, the training process did not finish despite spending more than 8
hours, as the Colab environment used for execution would timeout.
Future work includes implementing strategies to mitigate these limitations and challenges
effectively. Exploring alternative approaches, such as feature engineering to address data
skewness and using domain knowledge to impute missing features, could enhance the
model’s performance. Optimizing efficiency through parallel processing could also accelerate
the training of the model.
Conclusion
Airline delays are a prevalent issue in the aviation industry, with extensive consequences for
both airlines and passengers. Aside from the inconvenience experienced by travellers, these
delays incur huge financial losses for airlines, in the form of increased operational costs,
decreased productivity, and compensations. Additionally, delays tarnish the reputation of
airlines, decreasing customer loyalty and satisfaction.
Thus, using machine learning techniques for predicting airline delays has gained popularity.
By using historical flight data, weather forecasts, airport congestion patterns, and other
relevant details, machine learning models can predict delays to aid airline companies in
managing their operations, optimizing flight schedules to minimize disruptions, and
allocating resources strategically.
However, the models’ performance depends on the quality and comprehensibility of the
data, so having access to flight schedules, aircraft performance metrics, weather data, air
traffic information, and historical delay records along with their reasons would be highly
valuable.
The airline industry which is ever-active and dynamic, requires continuous
monitoring of delays and update of models with more information with time.
By investing in data-driven strategies, airlines can navigate the complexities of modern air
travel effectively and deliver a smooth and reliable experience for passengers.